onsdag, oktober 31, 2007

An interesting memory leak in JRuby

The last two days I had lots of fun with the interesting task of finding a major memory leak in JRuby. The only way I could reliably reproduce it was by running Mingle's test suite and see memory being eaten. I tried several approaches, the first being using jhat to analyze the heap dumps. That didn't really help me much, since all the interesting queries I tried to run with OQL had a tendency to just cause out of memory errors. Not nice.

Next step was to install SAP Memory Analyzer which actually worked really well, even though it's built on top of Eclipse. After several false starts, including one where I thought we had found the memory leak I finally got somewhere. Actually, I did find a memory leak in our method cache implementation. But alas, after fixing that it was obvious there was another leak in there.

I finally got SAP to tell me that RubyClasses was being retained. But when I tried to find the root chain to see how that happened I couldn't see anything strange. In fact, what I saw what the normal chaining of frames, blocks, classes and other interesting parts. And this is really the problem when debugging this kind of problem in JRuby. Since a leak almost always be leaking several different objects, it can be hard to pinpoint the exact problem. In this case I guess that the problem was in a large branch that Bill merged a few weeks back, so I tried going back to it and checking. Alas, the branch was good. In fact, since I went back 200 revisions I finally knew within which range the problem had to be. Since I couldn't find anything more from the heap dumps I resorted to the venerable tradition of binary search. Namely going through the revisions and finding the faulty one. According to log2, I would find the bad revision in less than 8 tries, so I started out.

After I while I actually found the problem. Let me show it to you here:
def __jtrap(*args, &block)
sig = args.first
sig = SIGNALS[sig] if sig.kind_of?(Fixnum)
sig = sig.to_s.sub(/^SIG(.+)/,'\1')
signal_class = Java::sun.misc.Signal
signal_class.send :attr_accessor, :prev_handler
signal_object = signal_class.new(sig) rescue nil
return unless signal_object
signal_handler = Java::sun.misc.SignalHandler.impl do
begin
block.call
rescue Exception => e
Thread.main.raise(e) rescue nil
ensure
# re-register the handler
signal_class.handle(signal_object, signal_handler)
end
end
signal_object.prev_handler = signal_class.handle(signal_object, signal_handler)
end
This is part of our signal handling code. Interestingly enough, I was nonplussed. How could trap leak? I mean, noone actually calls trap enough times to make it leak, right?

Well, wrong. Actually, it seems that ActiveRecord traps abort in transactions and then restore the original handler. So each transaction created new trap handlers. That would have been fine, except for the last line. In effect, in the current signal handler we save a reference to the previous signal handler. After a few iterations we will have a long chain of signal handlers, all pointing back, all holding a hard reference from one of the single static root sets in the JVM (namely, the list of all signal handlers). That isn't so bad though. Except a saved block has references to dynamic scopes (which reference variables). It has a reference to the Frame, and the Frame has references to RubyClass. RubyClass has references to method objects, and method objects have in some cases references to RubyProcs, which in turn have more references to Blocks. At the end, we have a massive leak.

The solution? To simple remove saving of the previous handler and simplify the signal handler.

QCon and OpenWorld

As mentioned before I will be in San Francisco next week for QCon, and the week after that for Oracle OpenWorld. I will be part of a panel debate at QCon and man a booth on Oracle OpenWorld. In fact, if you're attending OpenWorld you should visit ThoughtWorks booth at 343 Moscone South. Looking forward to seeing you there.

söndag, oktober 28, 2007

Michael Gira and Tim Bray

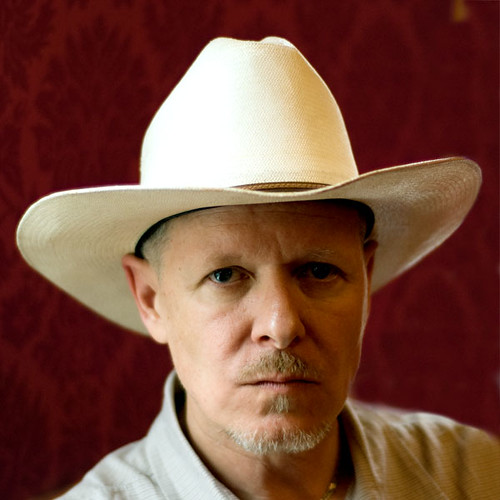
Doesn't Tim Bray and Michael Gira look very much alike? See for yourself:


I'm not sure if Tim has the voice of Michael, though. Anyway, I gotta say, warming up with preparty with Bill Hicks, and then a 90 minutes Michael Gira show was awesome.

Is this the wrong blog for this? Yeah, probably, but the Tim Bray inclusion warrants it. =)

fredag, oktober 26, 2007

Current state of Regular Expressions

As I've made clear earlier, the current regular expression situation has once again become impractical. To reiterate the history: We began with regular Java regex support. This started to cave in when we found out that the algorithm used is actually recursive, and fails for some common regexps used inside Rails among others. To fix that, we integrated JRegex instead. That's the engine 1.0 was released with and is still the engine in use. It works fairly well, and is fast for a Java engine. But not fast enough. In particular, there is no support for searching for exact strings and failing fast, and the engine requires us to transform our byte[]-strings to char[] or String. Not exactly optimal. Another problem is that compatibility with MRI suffers, especially in the multi byte support.

There are two solutions currently on the way. Core developer Marcin are working on a port of the 1.9 regexp engine Oniguruma. This port still has some way to go, and is not integrated with JRuby. The other effort is called REJ, and is a port of the MRI engine I did a few months back. I've freshened up the work and integrated it with JRuby in a branch. At the moment this work actually seems to go quite well, but there are some snags.

First of all, let me point out that this approach gives us more or less total multibyte compatibility for 1.8, which is quite nice.

When doing benchmarking, I'm generally using Rails as the bar. I have a series of regular expressions that Petstore uses for each requst, and I'm using these to check performance. As a first datapoint, JRuby+REJ is faster at parsing regexps than JRuby trunk for basically all regexps. This ranges from slightly faster to twice as fast.

Most of the Rails regexen are actually faster in REJ than in JRuby+trunk, but the problem is that some of them are actually quite a bit slower. 4 of the 22 Rails regexps are slower, by between 20 and 250% percent. There are also this one: /.*_f/ =~ "_fxxxxxxxxxxxxxxxxxxxxxxx" which basically runs about 10x slower than JRuby trunk. Not nice at all.

In the end, the problem is backtracking. Since REJ is a straight port of the MRI code, the backtracking is also ported. But it seems that Java is unusually bad at handling that specific algorithm, and it performs quite badly. At the moment I'm continuing to look at it and trying to improve performance in all ways possible, so we'll see what happens. Charles Nutter have also started to look at it.

But what's really interesting is that I reran my Petstore benchmarks with the current REJ code. To rehash, my last results with JRuby trunk looked like this:
controller :   1.804000   0.000000   1.804000 (  1.804000)
view : 5.510000 0.000000 5.510000 ( 5.510000)
full action: 13.876000 0.000000 13.876000 ( 13.876000)
But the results from rerunning with REJ was interesting, to say the least. I expected bad results because of the bad backtracking performance, but it seems the other speed improvements weigh up:
controller :   1.782000   0.000000   1.782000 (  1.782000)
view : 4.735000 0.000000 4.735000 ( 4.735000)
full action: 12.727000 0.000000 12.727000 ( 12.727000)
As you can see, the improvement is quite large in the view numbers. It is also almost there compared to MRI which had 4.57. Finally, the full action is better by a full second too. Again, MRI is 9.57s and JRuby 12.72. It's getting closer. I am quite optimistic right now, provided that we manage to fix the remaining problems with backtracking, our regexp engine might well be a great boon to performance.

Interesting times in JRuby land

The last week or two have been quite interesting. We are finally starting to see performance numbers that seem good enough. Take a look at Nick's posts here and here for more information on this. The second post contains some valuable tips. In particular, make sure to turn off ObjectSpace and run with -server. Both of these will improve your performance and scalability quite much.

Secondly, JRuby on Rails on Oracle Application Server. Nice, huh? I would imagine more interesting things coming out of all this.

But the end message seems to be that JRuby is really ready now. The 1.1 release looks like it's going to be something really amazing. I can't wait!

tisdag, oktober 16, 2007

Updated JRuby on Rails performance numbers

So, after my last post, several of us have spent time looking at different parts of Rails and JRuby performance. We have managed to improve things quite nicely since my last performance note. Some of the things changed have been JRuby's each_line implementation, JRuby's split implementation, a few other improvements, and some small fixes to AR-JDBC. After that, here are some new numbers for Petstore. Remember, the MRI numbers are for MRI 1.8.6 with native C MySQL. The JRuby numbers is with ActiveRecord-JDBC trunk and MySQL. (I'm only showing the best numbers of each). The number in bold is the most important one for comparison.

MRI   controller :   1.000000   0.070000   1.070000 (  1.430260)
JRuby controller : 1.804000 0.000000 1.804000 ( 1.804000)

MRI view : 4.410000 0.150000 4.560000 ( 4.575399)
JRuby view : 5.510000 0.000000 5.510000 ( 5.510000)

MRI full action: 8.260000 0.410000 8.670000 ( 9.574460)
JRuby full action: 13.876000 0.000000 13.876000 ( 13.876000)
As you can see, we are talking about 9.5s MRI to 13.8s for JRuby, which I find is a quite nice achievement if you look at the numbers from Friday. We are inching closer and closer. Both the view and the controller numbers are looking very nice. This is actually indicative of a nice trend - since general JRuby primitive performance is really good, the slowness in our Regular Expression engine is weighed up by much faster execution speed.

Once the port of Oniguruma lands, this story will almost certainly look very different. But even so, this is looking good.

söndag, oktober 14, 2007

JRuby discovery number one

After my last entry I've spent lots of time checking different parts of JRuby, trying to find the one true bottleneck for Rails. Of course, I still haven't found it (otherwise I would have said YAY in the subject for this blog). But I have found a few things - for example, symbols are slow right now, but Bill's work will make them better. And it doesn't affect Rails performance at all.

But the discovery I made was when I looked at the performance of the regular expressions used in Rails. There are exactly 50 of them for each request, so I did a script that checked the performance of each of them against MRI. And I found that there was one in particular that had really interesting performance when comparing MRI to JRuby. In fact, it was between 200 and a 1000 times slower. What's worse, the performance wasn't linear.

So which regular expression was the culprit? Well, /.*?\n/m. That doesn't look to bad. And in fact, this expression displayed not one, but two problems with JRuby. The first one is that any regular expression engine should be able to fail fast on something like this, simply because there is a string that always needs to be part of a string for this expression to match. In MRI, that part of the engine is called bm_search, and is a very fast way to fail. JRuby doesn't have that. Marcin is working on a port of Oniguruma though, so that will fix that part of the problem.

But wait, if you grep for this regexp in the Rails sources you won't find it. So where was it actually used? Here is the kicker: it was used in JRuby's implementation of String#each_line. So, let's take some time to look at a quick benchmark for each_line:
require 'benchmark'

str = "Content-Type: text/html; charset=utf-8\r\nSet-Cookie: aaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaaa "

TIMES=100_000

puts "each_line on small string with several lines"
10.times do
puts(Benchmark.measure{TIMES.times { str.each_line{} }})
end

str = "abc" * 15

puts "each_line on short string with no line divisions"
10.times do
puts(Benchmark.measure{TIMES.times { str.each_line{} }})
end

str = "abc" * 4000

puts "each_line on large string with no line divisions"
10.times do
puts(Benchmark.measure{TIMES.times { str.each_line{} }})
end
As you can see, we simple measure the performance of doing a 100 000 each_line calls on three different strings. The first one is a short string with several newlines, the second is a short string with no newlines, and the last is a long string with no newlines. How does MRI run this benchmark?
each_line on small string with several lines
0.160000 0.000000 0.160000 ( 0.157664)
0.150000 0.000000 0.150000 ( 0.160450)
0.160000 0.000000 0.160000 ( 0.171563)
0.150000 0.000000 0.150000 ( 0.157854)
0.150000 0.000000 0.150000 ( 0.154578)
0.150000 0.000000 0.150000 ( 0.154547)
0.160000 0.000000 0.160000 ( 0.158894)
0.150000 0.000000 0.150000 ( 0.158064)
0.150000 0.010000 0.160000 ( 0.156975)
0.160000 0.000000 0.160000 ( 0.156857)
each_line on short string with no line divisions
0.080000 0.000000 0.080000 ( 0.086789)
0.090000 0.000000 0.090000 ( 0.084559)
0.080000 0.000000 0.080000 ( 0.093477)
0.090000 0.000000 0.090000 ( 0.084700)
0.080000 0.000000 0.080000 ( 0.089917)
0.090000 0.000000 0.090000 ( 0.084176)
0.080000 0.000000 0.080000 ( 0.086735)
0.090000 0.000000 0.090000 ( 0.085536)
0.080000 0.000000 0.080000 ( 0.084668)
0.090000 0.000000 0.090000 ( 0.090176)
each_line on large string with no line divisions
3.350000 0.020000 3.370000 ( 3.404514)
3.330000 0.020000 3.350000 ( 3.690576)
3.320000 0.040000 3.360000 ( 3.851804)
3.320000 0.020000 3.340000 ( 3.651748)
3.340000 0.020000 3.360000 ( 3.478186)
3.340000 0.020000 3.360000 ( 3.447704)
3.330000 0.020000 3.350000 ( 3.448651)
3.350000 0.010000 3.360000 ( 3.489842)
3.350000 0.020000 3.370000 ( 3.429135)
3.350000 0.010000 3.360000 ( 3.372925)
OK, this looks reasonable. The large string is obviously taking more time to search, but not incredibly much time. What about trunk JRuby?
each_line on small string with several lines
32.668000 0.000000 32.668000 ( 32.668000)
30.785000 0.000000 30.785000 ( 30.785000)
30.824000 0.000000 30.824000 ( 30.824000)
30.878000 0.000000 30.878000 ( 30.877000)
30.904000 0.000000 30.904000 ( 30.904000)
30.826000 0.000000 30.826000 ( 30.826000)
30.550000 0.000000 30.550000 ( 30.550000)
32.331000 0.000000 32.331000 ( 32.331000)
30.971000 0.000000 30.971000 ( 30.971000)
30.537000 0.000000 30.537000 ( 30.537000)
each_line on short string with no line divisions
7.472000 0.000000 7.472000 ( 7.472000)
7.350000 0.000000 7.350000 ( 7.350000)
7.516000 0.000000 7.516000 ( 7.516000)
7.252000 0.000000 7.252000 ( 7.252000)
7.313000 0.000000 7.313000 ( 7.313000)
7.262000 0.000000 7.262000 ( 7.262000)
7.383000 0.000000 7.383000 ( 7.383000)
7.786000 0.000000 7.786000 ( 7.786000)
7.583000 0.000000 7.583000 ( 7.583000)
7.529000 0.000000 7.529000 ( 7.529000)
each_line on large string with no line divisions
Ooops. That doesn't look so good... And also, where is the last ten lines? Eh... It's still running. It's been running for two hours to produce the first line. That means that it's taking at least 7200 seconds which is more than 2400 times slower than MRI. But in fact, since the matching of the regular expression above is not linear, but exponential in performance, I don't expect this to ever finish.

There are a few interesting lessons to take away from this exercise:
  1. There may still be implementation problems like this in many parts of JRuby - performance will improve by quite much every time we find something like this. I haven't measured Rails performance after this is fixed, and I don't expect it to actually fix the whole problem, but I think I'll see better numbers.
  2. Understand regular expressions. Why is /.*?\n/ so incredibly bad for strings over a certain length? In this case it's the combination of .* and ?. What would be a better implementation in almost all cases? /[^\n]\n/. Notice that there is no backtracking in this implementation, and because of that, this regexp will have performance O(n) while the earlier one was O(n^2). Learn and know these things. They are the difference between usage and expertise.

fredag, oktober 12, 2007

Mystery: An exposé on JRuby performance

So, after Charlies awesome work yesterday (documented here), I felt it was time I put the story straight on general JRuby performance. It's something of a mystery. I'll begin by showing you the results of lots of different benchmarks and comparison to MRI. All these benchmarks have been run on my MacBook Pro, dual 2.33Ghz cores with 2Gb memory. JRuby revision is 4578, Java is Apple 1.6 beta, and Ruby version is 1.8.6 (2007-03-13 patchlevel 0). JRuby was ran with -J-server and -O.

Now, lets begin with the YARV benchmarks. The first values is always MRI, the second i JRuby. I've made the benchmark red when MRI is faster, and green when JRuby is faster.
bm_app_answer.rb:
0.480000 0.010000 0.490000 ( 0.511641)
0.479000 0.000000 0.479000 ( 0.478000)

bm_app_factorial.rb:
ERROR stack level too deep
2.687000 0.000000 2.687000 ( 2.687000)

bm_app_fib.rb:
5.880000 0.030000 5.910000 ( 6.151324)
2.687000 0.000000 2.687000 ( 2.687000)

bm_app_mandelbrot.rb:
1.930000 0.010000 1.940000 ( 1.992984)
2.752000 0.000000 2.752000 ( 2.876000)

bm_app_pentomino.rb:
84.160000 0.450000 84.610000 ( 88.205519)
77.117000 0.000000 77.117000 ( 77.117000)

bm_app_raise.rb:
2.600000 0.430000 3.030000 ( 3.169156)
2.162000 0.000000 2.162000 ( 2.162000)

bm_app_strconcat.rb:
1.390000 0.010000 1.400000 ( 1.427766)
1.003000 0.000000 1.003000 ( 1.003000)

bm_app_tak.rb:
7.570000 0.060000 7.630000 ( 7.888381)
2.676000 0.000000 2.676000 ( 2.676000)

bm_app_tarai.rb:
6.020000 0.030000 6.050000 ( 6.186971)
2.236000 0.000000 2.236000 ( 2.236000)

bm_loop_times.rb:
4.240000 0.020000 4.260000 ( 4.404826)
3.354000 0.000000 3.354000 ( 3.354000)

bm_loop_whileloop.rb:
9.450000 0.050000 9.500000 ( 9.678552)
5.037000 0.000000 5.037000 ( 5.037000)

bm_loop_whileloop2.rb:
1.890000 0.010000 1.900000 ( 1.936502)
1.039000 0.000000 1.039000 ( 1.039000)

bm_so_ackermann.rb:
ERROR stack level too deep
4.928000 0.000000 4.928000 ( 4.927000)

bm_so_array.rb:
5.580000 0.020000 5.600000 ( 5.709101)
5.552000 0.000000 5.552000 ( 5.552000)

bm_so_concatenate.rb:
1.580000 0.040000 1.620000 ( 1.647592)
1.602000 0.000000 1.602000 ( 1.602000)

bm_so_exception.rb:
4.170000 0.390000 4.560000 ( 4.597234)
4.683000 0.000000 4.683000 ( 4.683000)

bm_so_lists.rb:
0.970000 0.030000 1.000000 ( 1.036678)
0.814000 0.000000 0.814000 ( 0.814000)

bm_so_matrix.rb:
1.700000 0.010000 1.710000 ( 1.765739)
1.878000 0.000000 1.878000 ( 1.879000)

bm_so_nested_loop.rb:
5.130000 0.020000 5.150000 ( 5.258066)
4.661000 0.000000 4.661000 ( 4.661000)

bm_so_object.rb:
5.480000 0.030000 5.510000 ( 5.615154)
3.095000 0.000000 3.095000 ( 3.095000)

bm_so_random.rb:
1.760000 0.010000 1.770000 ( 1.806116)
1.495000 0.000000 1.495000 ( 1.495000)

bm_so_sieve.rb:
0.680000 0.010000 0.690000 ( 0.705296)
0.853000 0.000000 0.853000 ( 0.853000)

bm_vm1_block.rb:
19.920000 0.110000 20.030000 ( 20.547236)
12.698000 0.000000 12.698000 ( 12.698000)

bm_vm1_const.rb:
15.720000 0.080000 15.800000 ( 16.426734)
7.654000 0.000000 7.654000 ( 7.654000)

bm_vm1_ensure.rb:
14.530000 0.070000 14.600000 ( 15.137106)
7.588000 0.000000 7.588000 ( 7.589000)

bm_vm1_length.rb:
17.230000 0.090000 17.320000 ( 20.406438)
6.415000 0.000000 6.415000 ( 6.416000)

bm_vm1_rescue.rb:
11.520000 0.040000 11.560000 ( 11.736435)
5.604000 0.000000 5.604000 ( 5.603000)

bm_vm1_simplereturn.rb:
17.560000 0.080000 17.640000 ( 18.178065)
5.413000 0.000000 5.413000 ( 5.413000)

bm_vm1_swap.rb:
22.160000 0.110000 22.270000 ( 22.698746)
6.836000 0.000000 6.836000 ( 6.835000)

bm_vm2_array.rb:
5.600000 0.020000 5.620000 ( 5.675354)
1.844000 0.000000 1.844000 ( 1.844000)

bm_vm2_method.rb:
9.800000 0.030000 9.830000 ( 9.918884)
5.152000 0.000000 5.152000 ( 5.151000)

bm_vm2_poly_method.rb:
13.570000 0.050000 13.620000 ( 13.803066)
10.289000 0.000000 10.289000 ( 10.289000)

bm_vm2_poly_method_ov.rb:
3.990000 0.010000 4.000000 ( 4.071277)
1.750000 0.000000 1.750000 ( 1.749000)

bm_vm2_proc.rb:
5.670000 0.020000 5.690000 ( 5.723124)
3.267000 0.000000 3.267000 ( 3.267000)

bm_vm2_regexp.rb:
0.380000 0.000000 0.380000 ( 0.387671)
0.961000 0.000000 0.961000 ( 0.961000)

bm_vm2_send.rb:
3.720000 0.010000 3.730000 ( 3.748266)
2.135000 0.000000 2.135000 ( 2.136000)

bm_vm2_super.rb:
4.100000 0.010000 4.110000 ( 4.138355)
1.781000 0.000000 1.781000 ( 1.781000)

bm_vm2_unif1.rb:
3.320000 0.010000 3.330000 ( 3.348069)
1.385000 0.000000 1.385000 ( 1.385000)

bm_vm2_zsuper.rb:
4.810000 0.020000 4.830000 ( 4.856368)
2.920000 0.000000 2.920000 ( 2.921000)

bm_vm3_thread_create_join.rb:
0.000000 0.000000 0.000000 ( 0.006621)
0.368000 0.000000 0.368000 ( 0.368000)
What is interesting about these numbers is that almost all of them are way faster, and the ones that are slower are so by a quite narrow margin (except for the regexp and thread tests).

So, this is the baseline against MRI. Let's take a look at a few other benchmarks. These can all be found in JRuby, in the test/bench directory. When you run them, all of them generate 5 or 10 runs of all measures, but I've simply taken the best one for each. The repetition is to allow Java to warm up. Here are a few different benchmarks, same convention and running parameters as above:
bench_fib_recursive.rb
----------------------
1.390000 0.000000 1.390000 ( 1.412710)
0.532000 0.000000 0.532000 ( 0.532000)


bench_method_dispatch.rb
------------------------
Control: 1m loops accessing a local variable 100 times
2.830000 0.010000 2.840000 ( 2.864822)
0.105000 0.000000 0.105000 ( 0.105000)

Test STI: 1m loops accessing a fixnum var and calling to_i 100 times
10.000000 0.030000 10.030000 ( 10.100846)
2.111000 0.000000 2.111000 ( 2.111000)

Test ruby method: 1m loops calling self's foo 100 times
16.130000 0.060000 16.190000 ( 16.359876)
7.971000 0.000000 7.971000 ( 7.971000)


bench_method_dispatch_only.rb
-----------------------------
Test ruby method: 100k loops calling self's foo 100 times
1.570000 0.000000 1.570000 ( 1.588715)
0.587000 0.000000 0.587000 ( 0.587000)


bench_block_invocation.rb
-------------------------
1m loops yielding a fixnum 10 times to a block that just retrieves dvar
2.800000 0.010000 2.810000 ( 2.822425)
1.194000 0.000000 1.194000 ( 1.194000)

1m loops yielding two fixnums 10 times to block accessing one
6.550000 0.030000 6.580000 ( 6.623452)
2.064000 0.000000 2.064000 ( 2.064000)

1m loops yielding three fixnums 10 times to block accessing one
7.390000 0.020000 7.410000 ( 7.467841)
2.120000 0.000000 2.120000 ( 2.120000)

1m loops yielding three fixnums 10 times to block splatting and accessing them
9.250000 0.040000 9.290000 ( 9.339131)
2.451000 0.000000 2.451000 ( 2.451000)

1m loops yielding a fixnums 10 times to block with just a fixnum (no vars)
1.890000 0.000000 1.890000 ( 1.908501)
1.278000 0.000000 1.278000 ( 1.277000)

1m loops calling a method with a fixnum that just returns it
2.740000 0.010000 2.750000 ( 2.766255)
1.426000 0.000000 1.426000 ( 1.426000)


bench_string_ops.rb
----
Measure string array sort time
5.950000 0.060000 6.010000 ( 6.055483)
8.061000 0.000000 8.061000 ( 8.061000)

Measure hash put time
0.390000 0.010000 0.400000 ( 0.398593)
0.208000 0.000000 0.208000 ( 0.209000)

Measure hash get time (note: not same scale as put test)
1.620000 0.000000 1.620000 ( 1.646155)
0.740000 0.000000 0.740000 ( 0.740000)

Measure string == comparison time
2.340000 0.010000 2.350000 ( 2.368579)
0.812000 0.000000 0.812000 ( 0.812000)

Measure string == comparison time, different last pos
2.690000 0.000000 2.690000 ( 2.724772)
0.860000 0.000000 0.860000 ( 0.860000)

Measure string <=> comparison time
2.340000 0.010000 2.350000 ( 2.369915)
0.824000 0.000000 0.824000 ( 0.824000)

Measure 'string'.index(fixnum) time
0.790000 0.010000 0.800000 ( 0.808189)
1.113000 0.000000 1.113000 ( 1.113000)

Measure 'string'.index(str) time
2.860000 0.010000 2.870000 ( 2.892730)
0.956000 0.000000 0.956000 ( 0.956000)

Measure 'string'.rindex(fixnum) time
0.800000 0.000000 0.800000 ( 0.817300)
0.631000 0.000000 0.631000 ( 0.631000)

Measure 'string'.rindex(str) time
12.190000 0.040000 12.230000 ( 12.310492)
1.247000 0.000000 1.247000 ( 1.247000)


bench_ivar_access.rb
----
100k * 100 ivar gets, 1 ivar
0.500000 0.000000 0.500000 ( 0.582682)
0.340000 0.000000 0.340000 ( 0.340000)

100k * 100 ivar sets, 1 ivar
0.700000 0.010000 0.710000 ( 0.816724)
0.402000 0.000000 0.402000 ( 0.401000)

100k * 100 attr gets, 1 ivar
0.970000 0.000000 0.970000 ( 0.988212)
0.875000 0.000000 0.875000 ( 0.874000)

100k * 100 attr sets, 1 ivar
1.390000 0.010000 1.400000 ( 1.406535)
1.114000 0.000000 1.114000 ( 1.114000)

100k * 100 ivar gets, 2 ivars
0.490000 0.000000 0.490000 ( 0.506206)
0.344000 0.000000 0.344000 ( 0.344000)

100k * 100 ivar sets, 2 ivars
0.680000 0.000000 0.680000 ( 0.693064)
0.388000 0.000000 0.388000 ( 0.388000)

100k * 100 attr gets, 2 ivars
0.970000 0.000000 0.970000 ( 0.989313)
0.878000 0.000000 0.878000 ( 0.878000)

100k * 100 attr sets, 2 ivars
1.400000 0.000000 1.400000 ( 1.434206)
1.129000 0.000000 1.129000 ( 1.128000)

100k * 100 ivar gets, 4 ivars
0.490000 0.000000 0.490000 ( 0.502097)
0.340000 0.000000 0.340000 ( 0.340000)

100k * 100 ivar sets, 4 ivars
0.690000 0.000000 0.690000 ( 0.696852)
0.389000 0.000000 0.389000 ( 0.389000)

100k * 100 attr gets, 4 ivars
0.970000 0.010000 0.980000 ( 0.986163)
0.872000 0.000000 0.872000 ( 0.872000)

100k * 100 attr sets, 4 ivars
1.370000 0.010000 1.380000 ( 1.394921)
1.128000 0.000000 1.128000 ( 1.128000)

100k * 100 ivar gets, 8 ivars
0.500000 0.000000 0.500000 ( 0.519511)
0.344000 0.000000 0.344000 ( 0.344000)

100k * 100 ivar sets, 8 ivars
0.690000 0.000000 0.690000 ( 0.710896)
0.389000 0.000000 0.389000 ( 0.389000)

100k * 100 attr gets, 8 ivars
0.970000 0.000000 0.970000 ( 0.987582)
0.870000 0.000000 0.870000 ( 0.870000)

100k * 100 attr sets, 8 ivars
1.380000 0.000000 1.380000 ( 1.400542)
1.132000 0.000000 1.132000 ( 1.132000)

100k * 100 ivar gets, 16 ivars
0.500000 0.000000 0.500000 ( 0.523690)
0.342000 0.000000 0.342000 ( 0.343000)

100k * 100 ivar sets, 16 ivars
0.680000 0.000000 0.680000 ( 0.707385)
0.391000 0.000000 0.391000 ( 0.391000)

100k * 100 attr gets, 16 ivars
0.970000 0.010000 0.980000 ( 1.017880)
0.879000 0.000000 0.879000 ( 0.879000)

100k * 100 attr sets, 16 ivars
1.370000 0.010000 1.380000 ( 1.387713)
1.128000 0.000000 1.128000 ( 1.128000)


bench_for_loop.rb
----
100k calls to a method containing 5x a for loop over a 10-element range
0.890000 0.000000 0.890000 ( 0.917563)
0.654000 0.000000 0.654000 ( 0.654000)

All of this is really good, of course. Lots of green. And the red parts are not that bad either.

But here is the mystery. General Rails performance sucks. This test case can be ran by checking out petstore from tw-commons at RubyForge. There is a file called script/console_bench that will run the benchmarks. The two commands ran was: ruby script/console_bench production, and jruby -J-server -O script/console_bench ar_jdbc. With further ado, here are the numbers:
controller :   1.000000   0.070000   1.070000 (  1.472701)
controller : 2.144000 0.000000 2.144000 ( 2.144000)
view : 4.470000 0.160000 4.630000 ( 4.794336)
view : 6.335000 0.000000 6.335000 ( 6.335000)
full action: 8.300000 0.400000 8.700000 ( 9.597351)
full action: 16.055000 0.000000 16.055000 ( 16.055000)
These numbers plainly stink. And we can't find the reason for it. As you can see, most benchmarks are much better, and there is nothing we can think of that would add up to a general degradation like this. It can't be IO since these tests use app.get directly. So what is it? There is very likely to be one or two bottlenecks causing this problem, and when we have found it, Rails will most likely blaze along. But profiling haven't helped yet. We found a few things, but there is still stuff missing. It's an interesting problem.

My current thesis is that either symbols or regexps are responsible. I'll spend the day checking that.

Recent interviews

I have been doing several interviews recently, mostly in connection with my book. Here are the ones I know of right now:

torsdag, oktober 11, 2007

Grails eXchange, QCon SF and OpenWorld

It seems conference season is just coming up for me. I'll actually not be presenting at any of these events - just attending, being marketing and so on. First of, I'll run around at Grails eXchange in London next week as official ThoughtWorks representative. That is bound to be interesting.

I'll also attend QCon in San Francisco from 5th to 9th November. Directly following that I'll also be at Oracle's OpenWorld event from 11th November to 15th November. I'll have a fair amount of spare time in the evenings during the two weeks in San Francisco, so if anyone want to have a beer and discuss geeky things, feel free to mail me. Also, if anyone is interested in JRuby, I'm more or less always available to do talks on things like that.

Later on, I'll also be at JavaPolis in Antwerp, Belgium, in December.

See you out there.

onsdag, oktober 10, 2007

Announcing JRuby/LDAP

I have just released JRuby/LDAP, a new project within JRuby-extras, that aim to be interface compatible with Ruby/LDAP. That is, if you have a Ruby project written for Ruby/LDAP, you should be able to run it on JRuby without any changes.

This is a first release and some of the more obscure functionalities haven't been added yet.

Installation is easy:
jruby -S gem install jruby-ldap
If you're interested in the source, it's available on RubyForge, within the JRuby-extras project.

JRuby/LDAP uses JNDI to achieve nice LDAP access. You can also use standard Java ways (i.e. jndi.properties) to change the LDAP access implementation.

The code is BSD licensed.

tisdag, oktober 09, 2007

In favor of Ruby

Chad Wathington recently posted on the official ThoughtWorks Studios blog a post called Many Facets of Ruby. I would like to expand on some of the points on it, and how I see it. To be sure, what is posted on the TW Studios blog is the "official" ThoughtWorks views - whereas what I write in this blog is purely my own opinions, with no relationship to ThoughtWorks at all.

The point Chad writes about is that ThoughtWorks lately have been talking a lot about JRuby, in such a way that it's easy to get the impression that we as a company have chosen one implementation over the others. As Chad writes, that's not correct.

I've probably done the same thing in my blog. Obviously, I really like JRuby and hope it will work out well. I really like Rubinius effort and I predicted a while back that Rubinius may take over after MRI as the standard C Ruby implementation. But that doesn't mean I'm not interested in the the other approaches around. MRI and YARV definitely has strong points going for them (MRI and JRuby are still the only fully working implementations of Ruby). But when IronRuby, XRuby, Rubinius, YARV, Garden Points and Cardinal is more complete, the Ruby environment will be that much richer for it.

I'm not in this game for a specific implementation. I would use Ruby no matter if there was a JRuby or not. It's just that JRuby solves some of my problems, and allows me to hack on something that I know a segment of the Ruby user group will find useful. I'm in this for the language. I have chosen Ruby as my language, but the language is the same over the implementations. And it's going to be really exciting in the Ruby space the next few months.

lördag, oktober 06, 2007

Operator Overloading in Ruby

I really like the fact that Ruby has operator overloading. In many cases this feature is not very fitting in a language, but in Ruby it definitely has its place. So what's the difference? Why do people generally say that operator overloading in C++ is a bad thing, and that Java shouldn't have it? I believe the main reason is static typing. When you have static typing and combine that with a verbose language, operator overloading doesn't really fit in. You can't create DSL looking API's out of the language since the line noise usually make such efforts futile. And then you're left with only the bad parts of operator overloading.

In Ruby on the other hand, it fits very well. It actually makes sense to be able to redefine and add operators since there are many places where your code can be made much more readable with it. Of course, you always have to be careful and not go over board with it, but when used riht it improves readability to a large degree. A typical example of nice use of overloading is in Hpricot:
doc/:html/:body/:p/:img
Here the division operator have been overloaded to make it possible for you to write XPath like search strings beginning on a parsed Hpricot document.

Another place I really like is in the Ruby core library where the call method is usually overloaded as []. This makes sense if you think about it - in most cases the objects you can call on will take parameters and return a result based on the parameter. This can be mapped quite neatly to an Array or Hash containing values that are returned, and in fact you can imagine swapping out this restricted usage of an Array or Hash to something that you can call things on.
If the [] method is all you used for access, duck typing makes it easy to send in a Proc instead of an Array or Hash.

Another reason using [] can be nice, is since Ruby doesn't let you override (). If you want to emulate that kind of behavior, [] can act exactly the same if you want it to.

In the Ruby core, the more useful things that implement [] is Array and Hash, of course, UnboundMethod, BoundMethod, Proc and Continuation. This means that you can do something like proc{ puts "hello" }[] if you feel like it.

There are lots of other nice operators to overload in Ruby, though. Some of the better ones are unary + and unary -, all the common arithmetic operators, ||, &&, |, &, <, >, <=, >=, ~, =~, **, ==, === and a few others. The two things missing here is the ! and friends, and (). But of course, adding () wouldn't really work with the Ruby language. ! on the other hand should be overridable.

So, you should use operator overloading in Ruby, but be careful that it makes sense and actually gives you a good abstraction, not just something "cool".

onsdag, oktober 03, 2007

Know your Regular Expression anchors

As everyone knows, regular expressions are incredibly important in many programming tasks. So it pays to know some of the particulars of the regexp syntax. One example that bit me a while back was a simple oversight - something I did know but hadn't kept in mind while writing the bad code. Namely, the way the caret (^) works when used in a String with newlines in it. To be fair I've been using Java regexps for a while and that problem doesn't exist there.

To illustrate the difference, here is a program you can run in either MRI or JRuby. If running in JRuby you'll see that the Java version needs the flag MULTILINE to behave as Ruby does by default.
str = "one\nover\nyou"
puts "Match with ^"
str.gsub(/^o/) do |e|
p $~.offset(0)
e
end

puts "Match with \\A"
str.gsub(/\Ao/) do |e|
p $~.offset(0)
e
end


if defined?(JRUBY_VERSION)
require 'java'
regexp = java.util.regex.Pattern.compile("^o", java.util.regex.Pattern::MULTILINE)
matcher = regexp.matcher(str)
puts "Java match with ^"
while matcher.find()
p matcher
end

regexp = java.util.regex.Pattern.compile("\\Ao", java.util.regex.Pattern::MULTILINE)
matcher = regexp.matcher(str)
puts "Java match with \\A"
while matcher.find()
p matcher
end
end
So, what's the lesson here? Don't use caret (^) and dollar ($) if you actually want to match the beginning or the end of the string. Instead, use \A and \Z. That's what they're there for.

fredag, september 28, 2007

The first fully functional Ruby compiler

It's a glorious day. The JRuby compiler is now complete and functional. Without sacrificing interpreted mode. Read more in Charles blog, here.

torsdag, september 27, 2007

SQLServer is also stupid

I can't understand the problems database drivers have with whitespace where there shouldn't be any. It's clearly wrong...

So say that you create a table in SQLServer that is nullable. If you use DatabaseMetaData and do getColumns for that table, and check the nullable column, and fetch the value at index 18 - IS_NULLABLE. What you get back here is "YES" which is all according to the API. But if you by chance do the same thing for a column that is non-nullable - what value would you get then?
"NO ". Notice the space. Lovely. I *heart* databases.

... Someone asked me in response to my last blog post which database I would choose if I could. Hard question. I'd rather do without databases. But if I have to, I'd go with Mimer SQL which is probably the most SQL-compliant database ever, and really doesn't have WTF moments at all. It's small, it's from Sweden, and it's very nice.

onsdag, september 26, 2007

Oracle is stupid

I've just spent two days debugging and fixing AR-JDBC issues with Oracle. And let me tell you, those days haven't been fun. I am really unfond of Oracle at the moment. You probably saw my last post. Now, let me add a new point of insanity to the proceedings...

Say that you define a table like this:
create table companies (
firm_id integer default null references companies
);
Now, if you try to get the default value of the column firm_id in some manner (for example, you could use JDBC, DatabaseMetaData.getColumns, and getString(13) on the result). You could also use the OCI8 C interface. You would get the same result. Any guesses? What is the default value of the column firm_id? Some might say that it should be the String "null". Nope. It's the String "null ". Notice the space.

Now, if you instead defined your table like this:
create table companies (
firm_id integer default null
);
In this, what is the default value of the column firm_id? it's "null". Without a space. Yes, it varies. Yes, it actually varies based on the formatting of the SQL used to create the table. You could potentially use the Whitespace language to embed arbitrary programs in the null default value... Because if there is two blanks between the null word, and the next token, then that's what you will get from the default value. Notice that we used two totally different interfaces to get this information so it's obviously something that is saved in the database engine. Wow.

Is this insane? Is it crazy? Am I thoroughly disgusted by now?

Yes. And also, AR-JDBC finally runs all ActiveRecord tests with Oracle.

Lovely intermittent Oracle XE problem

I'm working on AR-JDBC support for Oracle. The easiest way to do this for me is to run Oracle XE inside Windows XP in Parallels. That works fine. Except for this dreaded message that started showing up and killing all my efforts: “ORA-12519, TNS:no appropriate service handler found”. I love Oracle error messages. They are so incredibly helpful!

At least in this case I found a solution to the problem on da Internet. I'm writing this blog post to make the information more obvious to Google.

It seems there is a bug in Oracle XE in the monitoring of processes that manifests this way. Nice. But you can fix it! Just open up your SQL console, write "connect system", submit your password and then write "ALTER SYSTEM SET PROCESSES=150 SCOPE=SPFILE;". After that, remember to restart the listener. And everything should be joy again.

måndag, september 24, 2007

Can bytecodes perform well?

I really need to write an answer to a comment that appeared on my post about Rubinius by Kragen Sitaker. It has two points in it, and I really want to address one of them at some length. So here goes. The comment read like this:

"It is byte code based. This means it's easier to handle performance."

If by "handle" you mean "not have".

"garbage collection/object memory can be switched out to use another algorithm"

In your dreams. I suspect you'll find out that the architecture isn't as clean as you think it is when you try to plug in some other existing garbage collector or object memory.

It sounds like a good project, but I don't think its advantages are going to be so enormous as you think they are.

Woha. That's hard to argue with. Isn't it? Or maybe not. Let's being with the second point. Is Rubinius architecture clean and decoupled enough to allow swapping of GC and object memory? My answer is a resounding yes. But of course you can go and look for yourself. Of course, it's possible to make a system where you can decouple the GC. Sun's standard JVM does this, for example. But the interesting point isn't whether Rubinius' hooks for this is clean enough, but if they are cleaner than MRI's. If you have ever tried to switch out the GC in MRI, you know that Rubinius beats MRI hands down in this regard. If not, you can ask Laurent Sansonetti at Apple, who have actually done most of the work to switch out the GC in MRI if that was a fun experience.

Let's see, what's next? Oh yeah. Bytecodes are always slow. No argument here. C++ will always beat a bytecode based engine. And C will almost always beat C++. And assembler (in the right hands) will usually beat C. But wait... Isn't Java bytecode based? And doesn't Java 6 perform on the same level as C in many cases, and in some cases performing better than C? Well, yes, it does... And wasn't Smalltalk always based on bytecodes? Most Smalltalk engines performed very well. Why is MRI switching to bytecodes for 1.9? And why has Python always been bytecode based? And why is the CLR bytecode based? Why was even Pascal using bytecodes back in the day? (OK, that is cheating... Pascal used bytecodes for portability, not performance, but it still worked well in that aspect too). Erlang is bytecode based.

Basically, there are some cases where a static language will benefit from straight compilation down to hardware machine codes. OCaML is a typical example of such a language. Due to the extremely stringent type requirements of the language, the emitted code is usually faster than C. But that is the exception, and only works for bondage-tightly typed languages. When talking dynamic languages, bytecodes is the real path to good performance. Granted, a naive implementation of a bytecode engine will not perform well. But that is true for a compiler too. The difference is that the part interpreting bytecodes is usually a quite small part of the whole runtime system, and it can be switched out for better performance, piecemal or all together.

There are other reasons. For example, statically typed languages like Java and the CLR family of languages use bytecodes because it gives the runtime system the opportunity to dynamically change the machine code running based on statistics and criteria found out during runtime. This means that your application will actually have better performance in the parts where it counts, and the parts that are not heavily used will not be optimized. (That's what HotSpot does, for example). This is not possible in a clean compilation to machine code. Java would never have had the performance it has now if it weren't for the bytecodes.

So please, stop spreading this myth. It is NOT true and it has NEVER been true.

Rubinius is important

I predict that parts of this blog posts will make certain people uncomfortable, annoyed and possibly foamy mouthed. If you feel that you're of this disposition, please don't read any further.

As I'm working on JRuby, I obviously think that JRuby is the best solution for many problems I perceive in the MRI implementation currently. I have been quite careful to never say anything along the lines that JRuby is better than anything else, though. I will continue with that stance. However, I won't restrict myself in the same way regarding Rubinius.

In fact, I'm getting more and more convinced that for the people that don't need the things Java infrastructure can give you, Rubinius is the most important project around, in Ruby-land. More than that, Rubinius is MRI done right. If nothing substantial changes in the current timeline and plans for Ruby 1.9.1, I predict that Rubinius will be the CRuby implementation of choice within 6 months. Rubinius is an implementation done the way MRI should have been. Of course, Matz have always focused on the language, not the implementation. I'm very happy about that, since it means that we have an outstanding language.

But still. Rubinius will win over MRI and YARV. I've had this thought for a while, and I'm finally more or less convinced that it's true. Of course, there are a few preconditions. The first and most important one is that Rubinius delivers 1.0 as planned, by the end of the year and that it doesn't have abysmal performance. Or if YARV would happen to be totally finished and perfectly usable in the same time frame, things might take a different turn.

Why is Rubinius so good, compared to the existing C implementations? There are a number of good reasons for this:
  • It is byte code based. This means it's easier to handle performance.
  • It has a pluggable, very clean architecture, meaning that for example garbage collection/object memory can be switched out to use another algorithm.
  • It is designed to be thread safe (though this is not really true yet), and Multi-VM capable.
  • It works with existing MRI extensions.
  • Most of the code is written in Ruby.
  • It gives you access to all the innards, directly from your Ruby code (stuff like MethodContexts/BlockContexts, etc).
  • The project uses Valgrind to ensure that the C code written is bullet proof.
Anyway. I put my money on Rubinius. Of course, that doesn't mean I don't think JRuby have a place to fill in the eco system. In fact, the real interesting question is what will happen when both Rubinius and JRuby have become more mature. I'd personally love to see more cooperation and sharing between the projects. Not a merging, since the goals are too separate, but it would be wonderful if JRuby could use the same Ruby code for all the primitive operations as Rubinius does.

Right now we have a simple Rubinius engine in JRuby, that can interpret and run some simpler byte codes from Rubinius.

JRuby and Rubinius are both extremely important. Right now I believe JRuby is more important, since it opens up a totally different market for Ruby, and gives the benefits of Java to Ruby. Rubinius has another place to fill.

Of course, being who I am, I have also looked into what would be required to port Rubinius to Java, using the same approach directly instead of going through JRuby. If you decide to use Java's Garbage Collector, Java Threads, and reuse the JRuby parser you would end up with about 40 files of C code to port. Most of these are extremely easy, and none is really that hard. And what you would end up with is something that would run the same things Rubinius does, but with the possibility of invoking Java code at the same time. (Of course, I hope that Evan reserves a block of about 8-16 bytecodes that can be implementation dependent - these Jubinius would use to interop with Java code).

Ruby+Erlang concurrency?

I keep reading from lots of people that you can't bolt Erlang's concurrency model on Ruby. But is this really true? MRI already has green threads. Adding a higher level of concurrency with the basic primitives of !, recv and spawn doesn't seem like a gigantic project. The main problem would be to prohibit access to shared memory between the spawned green threads, and avoid the GIL. But that doesn't seem to be that large of a problem. The main question is rather if this model would fit well with the Ruby language... Since Erlang was designed from the ground up with these primitives in mind, many of the libraries and functions work well with it. For example, pattern matching work exactly the same in recv as in function dispatch or case expressions.

On the other hand, the send, recv and spawn primitives in Gambit Scheme seems to work out really well even though the language is LISP in root (or maybe that's the reason?)

In fact, this is one of the few places where it would be harder to add something to JRuby than MRI. Since we can't control the full stack it would be very hard to implement anything resembling Erlang processes in Java. And Java threads would almost certainly be too heavy weight for this to work. Hmm.

Practical JRuby on Rails released!

Today my book Practical JRuby on Rails has been released by APress. It has got two forewords, one by Martin Fowler and one by Pat Eyler. And you can order it right now from Amazon here. Hopefully it will also be available in your closest computer book store!

söndag, september 23, 2007

What about Sun's Ruby strategy?

Wow. Today was a strange day for blog reading. I've already had several WTF moments. Or what do you say about 7 reasons I switched back to PHP after two years on Rails, where the first and most important reason seemed to be
IS THERE ANYTHING RAILS/RUBY CAN DO THAT PHP CAN’T DO? … (thinking)… NO.
Bloody hell. All programming languages in use today are Turing complete. Of course you can do exactly the same things in all of them. But I still don't program in Intercal that often.

Example number two: About JRuby and CPython performance. This blog post uses the Alioth language benchmark to show us that Python's C implementation is faster than JRuby. Of course, the JRuby version used in this comparison is 1.0, which is now almost 4 months old. Comparing the C implementation of one language with a Java implementation of another language seems kind of suspect anyway.

But these two examples is nothing compared to a post by Krishna Kotecha from yesterday. It's called Sun's Ruby strategy - Engage and Contain?. You should ge read it. It's actually quite amusing. I usually don't respond to other blog posts, and I don't usually quote in my blog. I'll do an except here, because there are several points in that post I want to elaborate on.

Compromise definitely seemed to be an underlying theme at RailsConf Europe. DHH’s keynote downplayed the need for evangelism - something I strongly disagree with. Rails has certainly made a lot of progress towards wider acceptance, but we’ve got a really long way to go before more companies start to adopt it, and I certainly don’t think turning down the evangelism and doing stealth deployments via JRuby is the answer.
There are really two interesting points in this paragraph. First of all the question of evangelism. I would say it's about time to turn it down. Actually, I've gotten the very real impression that the wild-eyed Rails evangelism is now turning people away from Rails rather than winning more "converts". Telling people about the advantages of Rails is still something that needs to be done, but the full fledged Rails marketing machine has already done it's work and should be turned down a notch.

The second point Krishna sneaked in there is about JRuby "stealth deployments". I'm pretty sure no one will ever do a real stealth deployment, and I find that concept totally wrong.

At RailsConf Europe 2007 however, Dave didn’t even specifically discuss Rails - and this seems to have been at the behest of the conference organizers. If this is the case, then the Rails community is already in trouble. Is this the price of Sun’s ’support’: that the community is no longer able to freely discuss the platform and what work needs to be done to get it accepted in the enterprise on its own terms?
Where does this particular conspiracy theory come from? Is there any evidence whatsoever that the organizers of RailsConf wanted Dave to not speak about the shortcomings of Rails? And even if that were the case, what's there to say that Sun is the reason for this? (Couldn't it have been IBM or ThoughtWorks, who were also Diamond sponsors?)

I have real problems with this attitude and approach. Selling Rails and Ruby, as “just a Java library” is a massive disservice to the technology, and simply means enterprise customers and decision makers won’t evaluate Ruby on its own merits.
What is important to realize is that the argument "just a Java library" will only ever be used in the case of organizations where there are good technology arguments for using JRuby on Rails, but non-technical management are making decisions based on what is most safe at the moment (see the Blub Paradox by Paul Graham). In most cases the "just a Java library" argument is useful only when talking about conservative environments who are standardized on a certain platform. And believe me, Krishna, there are many places where Java is the only allowed technology to be deployed. But in most cases JRuby will work fine for those IS departments. Is it really a disservice to the technology to make Rails and Ruby into something that can be used in even wider domains, removing cruft and bloatware at all places possible? Is it a disservice for the technology to be used in places where it would never enter without the help of JRuby?

But JRuby is not the best answer for Rails and Ruby developers.
I don't really understand this quote. Obviously Krishna have strong opinions about the subject, but stating something as a fact without telling the reasons for it being that way doesn't feel that interesting.

Serious Rails deployments (Mongrel not some Java Application Server) within enterprise environments may be difficult to achieve, but with the right political backing and developer persistence it can be done.
I must say I find it interesting that Mongrel is viewed as a serious deployment option when compared with a standard Java application server. The question here isn't how we should get enterprise environments to use Mongrel; rather, we should first decide if Mongrel really is a serious enough deployment environment for enterprises.

And this will benefit the whole Rails community - not just those who tie themselves to Sun’s technology platform.
I heard this rumor about Java being Open Source... Does that still mean tying yourself to "Sun's technology platform"?

And also, the vendor with the most to lose if Rails really does fulfill its potential in enterprise environments.
Why? What exactly does Sun lose if Rails win? Sun is using Rails and benefiting from it. And be careful about this: Rails is Rails, no matter if it runs on JRuby, MRI, YARV, Rubinius, IronRuby, Ruby.NET, XRuby, Cardinal or any other Ruby implementation now or ever. Rails is Rails.

Maybe I’ll start to believe when they start promoting Ruby on Rails at JavaOne, as opposed to promoting JRuby on Rails at RailsConf.
I guess you didn't attend JavaOne 2007, where both JRuby on Rails and Ruby on Rails had sessions, including promoting in one of the major keynotes. Sun is serious about Java being a multilingual platform. Of course they're spending money on getting these languages working on Java, but Sun is also giving support to both Rubinius and MRI. Would they really do that if this conspiracy theory is correct? For more information about that particular data point, take a look at Tim Bray's blog here: Rubinius Sprint.

Much more likely I think, is that we’ll see a Java based Rails alternative that ships with some new version of Java which has been designed to incorporate features from dynamic languages like Ruby and Python.
Java will almost certainly never ship with a web framework. That said, Phobos is one of the Sun projects for web development that uses JavaScript and incorporates features from Rails and Ruby, and also Python and other languages and frameworks.

And still, Sun doesn't seem to have a problem with Rails and Phobos living side by side. GlassFish includes support for both. And the Rails support doesn't make any changes to Rails, it doesn't require you to do anything extra, except that your application should run in JRuby. The latest version basically allows you to say "glassfish_rails start" while standing in your application directory.

...what compromises are we making for Sun’s involvement...
Yeah. What compromises are we making for Sun's involvement in the community? Except handling the fact that we get more commercial backing, more money in the ecosystem, more help from Sun engineers creating high quality Ruby code, a server that happens to host the SVN server for Ruby itself, and so on? Are these contributions? Sure. Are they commitments? Yeah. Are they something that will require compromises from the community? No, not really.

Sometimes I think that many in the Open Source world still panics as soon as a big company starts to make inroads. And yes, in many cases this hasn't worked out well. But we gotta see to the facts too. Some companies we will never be able to trust, but Sun has definitely been on the right side of the Open Source fence for a long time. Come on, people.

RailsConf Europe recap

I am finally back from a week of travel. Funny, it feels like much more than a week - but I guess that's because there were some interesting mishaps with some of the flights.

Last Sunday I traveled to Berlin to attend RailsConf Europe. I arrived kind of late and was really tired and out of it during the Monday. I didn't find most of the tutorials going on that enlightening - though it was fun to see David, Aslak and Dan present on RSpec together. I liked the mind map format they used instead of regular slides. Due to general tiredness and a really bad migraine I went to bed early. But before that I managed to see Dave Thomas introductionary keynote. It was interesting and extremely well presented; the theme was art and how it can help you as a programmer to use this metaphor to understand the things we do more closely. I didn't find anything really new in the presentation and I've heard several people say that they would prefer if Dave had spent some time talking specifically about Rails instead. I tend to agree.

The second day of the conference was really good. DHH delivered a keynote that basically said that there is nothing really new happening with Rails. After that it was time for sessions. I guess none of the first presentations made any real impact on me, since I don't remember what they were. After lunch I saw Nic Williams talk on meta programming; the talk was really fun. I didn't learn anything new, but I had a fun time while doing it.

Charles and Tom did their JRuby presentation. And I also saw Evan Phoenix Rubinius talk. It was very interesting - if I could stand programming in such a low level language as C, I would probably spend more time helping them than I do now. I will write more about Rubinius - probably tomorrow - I haven't really said everything I need to say here.

After the sessions there were more keynotes. Roy Fielding talked about REST. I gotta admit I didn't really hear much of it though, since I was spending time fixing an annoying bug. After that Craig McClanahan talked for a few minutes about Rails. It was very enlightening to know how well regarded Rails is within Sun. Some people seems to have a different view on all this though, seeing conspiracy and dirty dealings in the way Sun is working Rails. I'll need to cover that in a separate blog post too.

ThoughtWorks threw a party after the days session. That was very fun and well attended.

All the JRuby team attending (Charles, Nick, Tom and me) gathered together on the evening and did a JRuby Q&A BOF. Lots of people there, and a very free form of presentation made this one of the highlights for me. I had great fun and I hope the audience did too.

Finally the Wednesday... Cyndi Mithell from ThoughtWorks did a very nice keynote about why Ruby and Rails may be ready to cross the chasm and get a strong hold in the enterprise.

Koz and Marcel did a very good Rails Best Practices session. Down to earth, simple, totally useful advice on things to avoid in a Rails application and what to do instead.

And then it was time for my presentation about JRuby in ThoughtWorks. I think it went very well, but it became a little bit too corporate for my taste. I'll need to make sure that doesn't happen the next time. Maybe some more code in the presentation? =)

Most of the rest of the day was spent networking, hanging out in the exhibit hall and stuff like that. And then RailsConf was over.

My flight to Sweden from Berlin that evening didn't really happen as I had expected it too. Instead I had to spend the night on a hotel in Frankfurt and take an early flight from there to Gothenburg.

Overall I had a very good time at RailsConf this year. It's a worlds difference from RailsConf last year in London, which I felt was a real waste. This year the energy was high, much interesting things going on and lots of nice and smart people. Not as good as RailsConf in Portland earlier this year, but still very well worth attending. It seems that RailsConf has found a good balance in sessions. The only thing I can wish for would be more interesting choices for the tutorial day.

Ruby-DBI and JDBC

Last week I decided it was time to get Ruby-DBI working with JDBC. I resolved to get on it since it would be highly useful and probably not so hard either. But as it turned out I didn't really need to do anything. The work has already been done by Kristopher Schmidt. Very nice. So instead, this post will detail how to get it working with JRuby.

First download the Ruby-DBI distribution from RubyForge. Secondly, unpack. The third step is to configure and install it. Execute these commands inside the Ruby-DBI directory:
jruby setup.rb config --without=dbd_sqlite,dbd_sybase
jruby setup.rb setup
jruby setup.rb install
Now you should have Ruby-DBI installed, but no DBD drivers. Verify that it's actually installed by running "jirb -rdbi". The next step is to install the JDBC driver. First create a directory called $JRUBY_HOME/lib/ruby/site_ruby/1.8/DBD/Jdbc. Download Jdbc.rb and JdbcTypeConversions.rb and put them into this directory. Also make sure that the JDBC driver you want to use is on your CLASSPATH. Now you can create a script like this:
require 'dbi'

DBI.connect('DBI:Jdbc:mysql://localhost/test', 'test', 'test',
'driver'=>'com.mysql.jdbc.Driver') do |dbh|
p dbh.select_all('SELECT * FROM a_table')
end
Make sure that you include the name of the driver as done in this code. The first parameter should be the regular JDBC URI with DBI: first. In this case it's the test database on localhost I connecting to, using the test username and test password. More information about how Ruby-DBI can be used can be found by Google.

fredag, september 14, 2007

nXML in earnest

So, for various undisclosed reasons it's time to start seriously hacking XML. Now, the end artifact of this will be one of the few situations where XML is actually justified and makes this process better.

Of course, Emacs is a must for this challenge. I wouldn't even try doing it without a real editor. Now, the undisputed king of XML in Emacs is nXML-mode. I want it everywhere. So the first step is to bring out Trang and convert all DTD's into RelaxNG. Then edit schemas.xml and we're running. Well, except for the simple fact that Emacs refuses to load anything else than xml-mode automatically. That sucks.

So after lots of looking, it seems there is a new magic-mode-alist that can look at the beginning of a buffer and "magically" decide what kind of buffer we're dealing with. For some reason this behavior overrides my carefully laid out auto-mode-alist. Well. The solution for all you people is simple. Just add this snippet late in your loading process:
(setq magic-mode-alist
(cons '("<\\?xml " . nxml-mode)
magic-mode-alist))
(fset 'xml-mode 'nxml-mode)

torsdag, september 13, 2007

JavaScript ignorance

Put it down to my general ignorance - I've never realized that JavaScript has send/perform, and has had it for a long, long time. Of course, it only works for methods that exists on the object. Or? Is there any way of capturing non-existent method-calls/property look-ups like method_missing does?

Anyway, send:
function SendTester() {}
SendTester.prototype.foo = function() {
print("Hello");
};

new SendTester().foo();
var name = 'foo';
new SendTester()[name]();
Please, tell me something more cool I've been able to do in JavaScript in browsers for 5-10 years but didn't know about!

Concurrent DSLs

With all the current talk of DSLs and concurrency, what I find lacking is discussions about how to combine the two. Of course, domain specific languages are incredibly important - they create a logical separation between the implementors of the business logic, and the people implementing the actual implementation of the DSL. Does it seem like a strange idea to want many DSLs to be able to run parallel to each other? I would imagine that in most cases a DSL that describes business rules and business logic is sequential in the particulars, but that there are also larger concurrency possibilities. This should be totally invisible for the business rule implementor in most cases - the runtime system should be able to run everything as efficient as possible.

A natural way of looking at DSLs is as declarative languages. In many cases that's the way you write them (just look at the ActiveRecord API. it looks very declarative - it just happens to be implemented using imperative primitives). Now, if the language is truly declarative it should be side effect free. In the end, that isn't a real goal, but if it would be possible to clearly understand which parts of the rules are using side effects, the rest of the implementation should be able to run totally concurrently.

These kinds of things should be possible to implement in any language with sane multi threading/multi processing. That said, I wouldn't want the task of doing it with Java's concurrency primitives if I can help it. So what kind of tools would be helpful? Possibly Erlang of course, since it's already functional and that makes the identification of side effects much easier. Another possible alternative seems to be Gambit Scheme and Termite.

Anyone else thinking about these issues? Is there any research going on that would shed some light on it? And further, what's the next step? Why haven't this question already been discussed? It seems to be well time for it now.

måndag, september 10, 2007

Should Ruby have optional typing and compiler directives?

I'm starting to miss a few Common Lisp special forms more and more. To be more specific, I miss the family of declare/declaim/proclaim. I think a version of them could actually be extremely useful for Ruby. The current approach to String encodings in 1.9.1 uses a "pragma" inside of a comment on the first line of a Ruby file, like this:
# coding=utf-8
This works fine for coding, I guess, but I would like to have something more general - something that can be used inside of code too. As a typical example of the kind of thing I would love to be able to do, here is an example of a Common Lisp implementation of fib:
(defun fib (n)
(cond
((or (eql n 0) (eql n 1)) n)
(t (+
(fib (- n 1))
(fib (- n 2))))))
As you can see, it's the standard implementation. But, after this implementation is finished, I can continue by adding declarations:
(defun fib (n)
(declare (integer n))
(cond
((or (eql n 0) (eql n 1)) n)
(t (+
(fib (- n 1))
(fib (- n 2))))))
This will help the compiler by telling that the n-argument is always an integer. You can also add more information to the declaration:
(defun fib (n)
(declare (integer n)
(optimize (safety 0)
(speed 3)))
(cond
((or (eql n 0) (eql n 1)) n)
(t (+
(fib (- n 1))
(fib (- n 2))))))
Now we're looking at some directives about how the compiler prioritize between safety and speed. You can also add directives for how much debug information should be retained or if the compiler should improve speed or size. All of this is interesting, but if I compile it with SBCL I'll get a few warnings. I've specified I want a high level of speed and low safety, but there are many optimizations that SBCL still can't do, so it warns about them. In most cases it's because there is no way to see if the result of the fib-operations return numbers, floats or rationals. If fib is seen as a bottleneck, the way to fix this is to add declarations inline the code in the style of this: (the numeric (- n 1)) and so on. This will allow the compiler to generate the best code possible.

Now, these kinds of changes are quite intrusive, and they aren't really something you want all over your code base. That's why you can do these declarations selectively, at only the places where it makes sense from a performance perspective to do it. By doing it correctly, Common Lisp code can be compiled to be incredibly efficient and fast, but very clean since in most cases you don't add the type declarations at all.

This is also why Common Lisp is very good for rapid prototyping. You can get something working really quickly, but you can also change the code to be efficient later on with quite small changes.

I guess you all wonder what this has got to do with Ruby. Or maybe you don't. Anyway - I want this in Ruby, or something equivalent to it. Not necessarily the exactly same thing, but something which in a standard way can add type declarations and also other things that can be interesting to know from a compiler perspective. It needs to be a keyword with specific syntax so the information is available before runtime. It should probably be used for the encoding declarations too, so it should be possible to use either at top level, or within class declarations , or method definitions. What do I want to be able to do? Well, type declarations is the first one. The second is compiler directives that can help improve code more than is possible right now. A typical example could look like this, maybe:
declare encoding: utf-8

def test_one(first, second, *rest)
declare type: [Fixnum first, Enumerable second, Array rest]
declare return: Fixnum
declare compiler: [no-bindings, no-eval, no-closures]

puts "hello"
return 1+1
end
This code includes several things that would be very useful to know and would allow compilers like JRuby, XRuby, YARV, Rubinius and IronRuby to produce much better code. If we know that the arguments should always be specific types we can declare this and hopefully get better results. The return value is also usually the same type and declaring this can make code that uses this method more efficient. Finally, the compiler declarations will help with some of the pain points for currently compiling things efficiently. If no bindings, or evals or closures are used, the code generated will be much better.

This kind of information would be very useful not only for the compiler but also for tool support. If you know something should always be a specific type, you can add that as a declaration and things will automatically function better.

I know that this is kind of un-Ruby like, but I really believe there is great value to be had by adding this kind of declarations.

JavaScript 2

After all discussions about the NBL and all surrounding issues, I realized I haven't actually looked at what JavaScript 2/ECMAScript 4 will contain. I decided to do some research. What I found was mostly very old (2 years or so), but very enticing. If only half of it comes true, JS2 will be a power house. Of course, the C inspired JS syntax is still kind of repugnant, and it's hard to see any kind of general purpose macro facility working on it. Pattern matching is the only reasonable way of getting macros in there, me thinks, and that just doesn't pack the same power.

But still, there are seriously nice things there:
  • Classes (the classic kind), packages and namespaces
  • Destructuring
  • Generators and iterators
  • A real numeric tower
  • Optional static typing
The end result is that JS2 will look much more like Java, but pack greater power in many ways. I wouldn't say that I agree about JS2 being the NBL, but we're still talking some nice innovation here.

ThoughtWorks Immersion

I've just come back from Bangalore, India where I spent two weeks with intense learning, much socializing and incredible amounts of fun. In short, I've attended ThoughtWorks Immersion. I found it to be a singular experience, and something that will be immensely helpful during my career at ThoughtWorks.

So what is Immersion? Basically, it's two weeks of learning that all ThoughtWorkers go through. The aim is not really to teach technical concepts or specific ways of working, but more to establish a common vocabulary, get everyone to understand the history of ThoughtWorks, and also give insight into all parts of the organization. How everything works and how we do things. A large part also is about what makes ThoughtWorks different from other companies, both in the way we do things but also the why of it all. The values TWers should share and what makes TW a unique place to work.

I feel I've learned incredibly much. The two weeks away from regular work was hard but definitely worth it. I wish all companies had something like this - but I guess that this is one of the ways that make TW a very different place.

The learning side was important, but the social aspect probably even more so. I now have 13 new friends within ThoughtWorks, spread all over the world. We had a good time together. Also, Bill Kimmel and Naresh Jain turned out to be outstanding teachers and very nice people to boot.

Of course, the stay in Bangalore got even more productive when Roy Singham, Chad Wathington, Cyndi Mitchell and a few other people arrived there. I spent some time with them, planning and scheming.

Meeting Håkan Råberg and seeing the cool stuff he's working on (still secret) was also very nice.

All in all, two weeks well spent.

Upcoming

Next week I'll be in Berlin for RailsConf EU. I'll be speaking about JRuby at ThoughtWorks, and hopefully I'll meet lots of you there.

ThoughtWorks is actually massively involved in this RailsConf, and I'm hoping for the same kind of energy I observed at RailsConf in Portland.

See you next week!

söndag, augusti 26, 2007

On the road again...

Bangalore, India - here I come!

fredag, augusti 17, 2007

My presentation from JavaBin

If someone is interested in the presentation I did at javaBin in Bergen and Oslo, it can be found here.

torsdag, augusti 16, 2007

An introduction to categories of type systems

Since the current world is moving away from languages in the classical imperative paradigm, it's more and more important to understand the fundamental type differences between programming languages. I've seen over and over that this is still something people are confused by. This post won't give you all you need - for that I recommend Programming Language Pragmatics by Michael L. Scott, a very good book.

Right now, I just wanted to minimize the confusion that abounds surrounding two ways of categorizing programming languages. Namely strong versus weak typing and dynamic versus static typing.

The first you need to know is that these two typings are independent of each other, meaning that there are four different types of languages.

First, strong vs weak: A strongly typed language is a language where a value always have the same type, and you need to apply explicit conversions to turn a value into another type. Java is a strongly typed language. Conversely, C is a weakly typed language.

Secondly, dynamic vs static: A static language can usually be recognized by the presence of a compiler. This is not the full story, though - there are compilers for Lisp and Smalltalk, which are dynamic. Static typing basically means that the type of every variable is known at compile time. This is usually handled by either static type declarations or type inference. This is why Scala is actually statically typed, but looks like a dynamic language in many cases. C, C++, Java and most mainstream languages are statically typed. Visual Basic, JavaScript, Lisp, Ruby, Smalltalk and most "scripting" languages are dynamically typed.

See, that's not too hard, is it? So, when I say that Ruby is a strongly, dynamically typed language, you know what that means?

C is a actually an interesting beast to classify. It's the only weakly, statically typed language I can think of right now. Anyone has any more examples?

To find out more, read the book above, or look up "Type systems" on Wikipedia.

Plans - Oslo and Sweden

I'm right now in Bergen, but I'm flying to Oslo later today - I'll basically land and head directly to the javaBin meeting. Afterwards I'm up for beers or something, if someone wants to.

On Friday I'm heading for Sweden. For purely recreational purposes. I'll be in Gothenburg, Malmö and Stockholm for a week or so, so if someone feels like saying hi, do tell. I always like good discussions about programming languages. And other things as well, in fact.

tisdag, augusti 14, 2007

Comprehensions in Ruby

Now, this is totally awesome. Jay found a way to implement generic comprehensions in Ruby. In twenty lines of code. It's really quite obvious when you look at it. An example:
(1..100).find_all &it % 2 == 0
%w'sdfgsdfg foo bazar bara'.sort_by(&its.length).map &it.reverse.capitalize

%w'sdfgsdfg foo bazar bara'.map &:to_sym
%w'sdfgsdfg foo bazar bara'.map &it.to_sym
Now, the last two lines are what I like the most. The Symbol to_proc tric is widely used, but I actually think the comprehension version is more readable. It's even better if replacing "map " with "collect".

This is actually real fun. You can link how many methods you like - you can send arguments to the methods, you can send blocks to them, you can link and nest however you want. It apples for Arrays, Sets, Hashes - everything you can send a block to can use this, so it's not limited to collections or anything like that.

I think it's really, really cool, and it should be part of Facets, ActiveSupport, hell, the Ruby core library. I want it there.

Now, the only, only, only quibble I have with it... He choose to call it "The Methodphitamine". You should actually use 'require "methodphitamine"'. It's a gem. I love it. But I hate the name. So, read more in his blog, here: http://jicksta.com/articles/2007/08/04/the-methodphitamine.

New double-operators in Ruby

So, I had a great time at the London RUG tonight, and Jay Phillips managed to show me two really neat Ruby tricks. The first one is in this post, and the next one is about the second.

Now, Ruby has a limited amount of operator overloading, but that is in most cases limited by what is predefined. There is actually a category of operators that are not available be the regular syntax, but that can still be created. I'm talking about almost all the regular single operators followed by either a plus sign or a minus sign.

Right now, I don't have a perfect example of where this is useful, but I guess someone will come up with it. You can use it in all cases where you want to be able to use stuff like binary ++, binary --, /-, *+, *-, %-, %+, %^, and so forth.

This trick makes use of the parsing of unary operators combined with binary operators. So, for example, this code:
module FixProxy; end

class String
def +@
extend FixProxy
end
alias __old_plus +
def +(val)
if val.kind_of?(FixProxy)
__old_plus(" BAR " << val)
else
__old_plus(val)
end
end
end

puts("Foo" ++ "Baz")
will actually output "Foo BAR Baz".

I'm pretty certain someone kind find a good use for it.

måndag, augusti 13, 2007

London RUG tonight

Anyone showing up for the London RUG tonight? Seems like it will be interesting: Ruby2Ruby and ParseTree, and also Jay Phillips about Adhearsion (which is really cool).

I will not be presenting, so don't worry about that. =)

Hope to see you there.

fredag, augusti 10, 2007

ActiveHibernate is happening

So, it seems someone stepped up to the challenge and started working on ActiveHibernate from me initial idea. The code got pushed online a while back and I have finally had the time to look at it. Over all it looks really nice.

Of course, it's very early times. I've submitted some patches making the configuration aspect easier and more AcitveRecord like - but it's going to be important to have access to all the features of Hibernate too. When in the balance, I don't think we should aim for total ActiveRecord equivalence.

Read more here and find the Google Code project here.

I would encourage everyone interested in a merger between Rails and Hibernate to take a look at this. Now is the time to come with advice on how it should work, what it should do and how it should look like.

RailsConf Europe

I am a speaker at RailsConf Europe in Berlin. I'm going to talk about JRuby on Rails at ThoughtWorks. Hopefully many of you'll make it there! As far as I know, it seems the whole core JRuby team may be together for the first time ever, so it's going to be a great conference for JRuby.

See you in Berlin!

torsdag, augusti 09, 2007

NetBeans Ruby support

It's very nice. Each time I get an update from Tor Norbye's blog with screenshots from the NetBeans Ruby support I see a new interesting feature. What I saw this time (here) was that the gotcha from my entry called "Ruby is hard" can now be detected by NetBeans. It's not really too hard, since NetBeans have the parse trees. But it's still a very nice feature to have in your editor.

But I ain't switching from Emacs yet...

onsdag, augusti 08, 2007

Ruby is hard

I have been doing Ruby programming for several years now, and been closely involved with the JRuby implementation of it for about 20 months. I think I know the language pretty well, and I think I have for a long time. This has blinded me to something which I've just recently started to recognize. Ruby is really hard. It's hard in the same way LISP is hard. But there are also lots of gotchas and small things that can trip you up.

Ruby is a really nice language. It's very easy to learn and get started in, and you will be productive extremely quickly, but to actually master the language takes much time. I think this is underestimated in many circles. Ruby uses lots of language constructs which are extremely powerful, but they require you to shift your thinking - especially when coming from Java, which many current Ruby converts do.

As a small example of a gotcha, what does this code do:
class Foo
attr_accessor :bar
def initialize(value)
bar = value
end
end

puts Foo.new(42).bar
If your answer is that it prints 42, you're wrong. It will print nil. What's the necessary change to fix this? Introduce self:
class Foo
attr_accessor :bar
def initialize(value)
self.bar = value
end
end

puts Foo.new(42).bar
You could argue that this behavior is annoying. That it's bad. That it's wrong. But that's the way the language works, and I've seen this problem in many code bases - including my own - so it's worth keeping an eye open for it.

Why does it happen? Well, the problem is this, when the Ruby parser finds a word that begins with an underscore or a lower case letter, and where that word is followed by an equals sign, there is no way for the parser to know if this is a method call (the method foo=) or a variable assignment. The fall back of the parser is to assume it is a variable assignment and let you specify explicitly when it should be a VCall. So what happens in the first example is that a new local variable called "bar" will be introduced and assigned to.

JRuby presentation in Bergen

Next Wednesday (the 15th) I will present about JRuby in Bergen. I mentioned this in an earlier post. More information can be found here: http://www4.java.no/web/show.do?page=42;7&appmode=/showReply&articleid=5493.